I am trying to use the Content.GetById() command in a custom IContentFinder following the docs example. The example, and VS Intellisense, says to give it an int but I can’t find an actual int ID for the content node just a GUID. Where am I supposed to find this int ID from?
I think you should be able to pass the Guid of the content as well. If not, UmbracoContext.Content.GetById({guid}) should solve it definitly.
Greetings
The goal is to NOT use id’s anymore because they are usually not the same between environments. However, keys (guid) are almost guarantee to be unique, so that’s what we are using these days. You can’t see the id in the backoffice anymore, but you can see the guid.
There are a few things here and there that still want an int id, but it’s less and less common. So just use the key anywhere you can. GetById() also accepts a guid.
Int Id’s still used in the DB for primary keys.. as Guids aren’t suitable..
Wonder if UUIDv7 could be the answer to that?
How UUID v7 Works
UUID v7 consists of three segments: a 48-bit timestamp, a 12-bit random segment, and a 62-bit random segment.
- The 48-bit timestamp represents the number of milliseconds since the Unix epoch.
- The 12-bit random segment adds randomness to ensure uniqueness within the same millisecond,
- while the 62-bit random segment ensures overall uniqueness, offering 122 bits of entropy.
This is particularly useful for databases where insertion order is important and can help in performance optimizations.
ET9 and UUIDv7
In .NET 9, UUIDv7 support was introduced which provides a way to generate ordered UUIDs based on timestamp. Developers can use the Guid.CreateVersion7() function to generate UUIDv7 with timestamp customization support.
Guid uuidV7 = Guid.CreateVersion7(); // Use DateTime.UtcNow
I don’t see how UUID relate to this issues or helps at all. Can you please clarify?
If I put the GUID raw or surounded by quotes it errors out with “Can’t convert from string to int”.
umbracoContext.Content.GetById("GUID");
where umracoContext is the result of `_umbracoContextAccessor.TryGetUmbracoContext(out var umbracoContext)’
Am I using the wrong context here?
Hi @Eaglef90
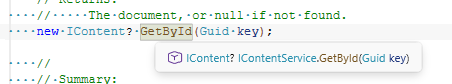
The IPublishedContentCache has an overload that accepts an int or a Guid:
You can’t pass the GUID as a string, it needs to be an actual Guid type, created using Guid.Parse() or Guid.TryParse().
As @Luuk says, don’t use the IDs and I would go as far to say don’t hard-code any IDs (ints or GUIDS), get them from appSettings if possible, or better still traverse the published content cache to get the node you need that way (if you know where it resides and does not result in lots of lookups).
Justin
I have not really dealt with GUIDs before so I was not awayre of the Guid.Parse() command thanks.
You also have a good point on the “don’t hard-code”, it made me realize this is a muti-site install and some sites will have there own news sections so if I hard-code this one ID that will mess them up. Now to figure out how to find the right news node while in my IContentFinder
A few suggestions:
- You get the first node of type ‘news overview’ it finds under the root of the current site.
- You create a picker somewhere where you pick the ‘correct’ newsoverview. Especially useful if you have multiple newsoverviews
I was able to build out code to grab the request’s hostname and pull the root node matching it then I pulled the news page under that node. I is all working on the routing end. Now it is time to build the template out to deal with everything for display
If you are already in a ‘routed request’ (and I think the ContentFinder would qualify) and you have a umbraco context available, you can get the root node’ where the cultures and hostnames are set on like this:
var rootId = umbracoContext.PublishedRequest?.Domain?.ContentId;
Manually getting the hostname from the request and matching should not be necessary.
That is almost the exact line of code I use. This is the final code I ended up with that works. How effecant is it? Probibly not at all since I am not used to working this deep but it works and I did it without AI (well the regex generator site I used might have used AI to make the regex for me) and I am proud of it. I did have to bug you all a bunch but I am learning.
    public sealed partial class NewsArchiveContentFinder(IUmbracoContextAccessor umbracoContextAccessor, IDocumentUrlService documentUrlService) : IContentFinder
    {
        [GeneratedRegex(@"\A/news/(?<year>[0-9]{4})/(?<month>0[1-9]|1[0-2])/?\z", RegexOptions.CultureInvariant | RegexOptions.ExplicitCapture | RegexOptions.IgnoreCase)]
        private static partial Regex NewsArchivePathRegex { get; }

        public Task<bool> TryFindContent(IPublishedRequestBuilder request)
        {
            var match = NewsArchivePathRegex.Match(request.Uri.GetAbsolutePathDecoded());
            if (!match.Success || !umbracoContextAccessor.TryGetUmbracoContext(out var umbracoContext)) return Task.FromResult(false);
            var year = int.Parse(match.Groups["year"].ValueSpan);
            var month = int.Parse(match.Groups["month"].ValueSpan);
            var rootNodeID = request.Domain?.ContentId;
            if (rootNodeID is null) return Task.FromResult(false);
            var rootNode = umbracoContext.Content.GetById(rootNodeID.Value);
            var newsNodeID = rootNode.FirstChild<NewsHomePage>().Key;
            var content = umbracoContext.Content.GetById(newsNodeID);
            if (content is null) return Task.FromResult(false);
            request.SetPublishedContent(content);
            return Task.FromResult(true);
        }
    }
}
I personally think that not using AI is not something to be necessarily ‘proud’ about. What I am proud about, is that you want to understand what you are doing and that is the right way to go about it.
But I personally think you should AI to do your research and to find the services that you can use most effectively. The question whether this is ‘effecient’ is something that AI can anwer really well. So I think that as long as you don’t just use anything that AI tells you, but use it as a research and verification tool, you should be fine.
I have 20+ years of development experience and Claude for instance is exceptionally well in following the source code of Umbraco and telling me if what I do is good or bad for performance of if it has any side effects. Especially scoping and transactions is a horror in Umbraco to understand well.
I did let Claude analyze your code sample and it give me this:
Good things first: [GeneratedRegex] on a partial property is a nice choice.
The regex is built at compile time, so it is fast. A content finder runs on
every request that does not match a page, so speed matters here. You also check
the regex before you use UmbracoContext. That is the right order.
Three things I would fix:
1. Two places can throw a NullReferenceException
GetById() returns IPublishedContent? and FirstChild<NewsHomePage>()
returns T?. Both can be null. So .Key can throw.
This is worse than it looks. If a content finder throws, Umbraco does not try
the next finder. The visitor gets a 500 error page.
When can they be null? The root node is null if it is not published (a domain
stays on a node even after you unpublish it). The child is null if nobody made
a NewsHomePage yet.
Turn on nullable reference types. The compiler will show you both problems.
2. year and month are read, but never used
You parse them into variables and then do nothing with them. So /news/2024/05
and /news/1999/01 show exactly the same page.
Two problems:
- The template cannot know which month the visitor asked for.
- Every year/month combination is a working URL with the same content. Google
sees this as duplicate content. There is also no 404 for a month with no news.
Save the period in HttpContext.Items (or in a small scoped service) so your
view model can read it.
3. It stops working when a domain has a path
request.Uri.GetAbsolutePathDecoded() gives you the complete path. If you use
domains like example.com/en, then the path is /en/news/2024/05. Your regex
starts with \A/news/, so it never matches.
Fix it like this:
var path = request.Domain is not null
    ? DomainUtilities.PathRelativeToDomain(request.Domain.Uri, request.AbsolutePathDecoded)
    : request.AbsolutePathDecoded;
Also: when request.Domain is null, your code returns false. So the finder does
nothing on a site without hostnames. Better to use the first root node instead.
Smaller things
request.AbsolutePathDecodedalready exists onIPublishedRequestBuilder.
It is calculated one time in the constructor. So you do not need to decode
the URI again on every request.FirstChild()already gave you the node. Reading.Keyand then calling
GetById()asks the cache for the same node a second time. You can delete
those two lines and use the node directly.IDocumentUrlServiceis injected, but you never use it.FirstChild<T>()is the “friendly” version. It gets its services from
StaticServiceProvider. That is fine in a view. But your class already uses
constructor injection, so injectIDocumentNavigationQueryServiceand
IPublishedStatusFilteringServiceand pass them yourself.- Give
request.CulturetoFirstChild. Umbraco sets the culture from the
domain before the finders run, so the value is ready for you. - The
/?in your regex does nothing. TheUrion the builder never has a
trailing slash. - Rename
rootNodeIDtorootNodeId, and giveint.Parsea
CultureInfo.InvariantCulture, or the analyzer will warn you (CA1305).
So an updated code example is this:
public sealed partial class NewsArchiveContentFinder(
    IUmbracoContextAccessor umbracoContextAccessor,
    IDocumentNavigationQueryService navigationQueryService,
    IPublishedStatusFilteringService publishedStatusFilteringService,
    IHttpContextAccessor httpContextAccessor) : IContentFinder
{
    public const string PeriodKey = "NewsArchivePeriod";

    [GeneratedRegex(@"\A/news/(?<year>[0-9]{4})/(?<month>0[1-9]|1[0-2])\z",
        RegexOptions.CultureInvariant | RegexOptions.ExplicitCapture | RegexOptions.IgnoreCase)]
    private static partial Regex NewsArchivePathRegex { get; }

    public Task<bool> TryFindContent(IPublishedRequestBuilder request)
        => Task.FromResult(TryFind(request));

    private bool TryFind(IPublishedRequestBuilder request)
    {
        if (!umbracoContextAccessor.TryGetUmbracoContext(out IUmbracoContext? umbracoContext))
        {
            return false;
        }

        // A domain can include a path (example.com/en), so match without that part.
        var path = request.Domain is not null
            ? DomainUtilities.PathRelativeToDomain(request.Domain.Uri, request.AbsolutePathDecoded)
            : request.AbsolutePathDecoded;

        Match match = NewsArchivePathRegex.Match(path);
        if (!match.Success)
        {
            return false;
        }

        IPublishedContent? siteRoot = request.Domain is not null
            ? umbracoContext.Content.GetById(umbracoContext.InPreviewMode, request.Domain.ContentId)
            : FirstRoot(umbracoContext);

        NewsHomePage? newsHome = siteRoot?.FirstChild<NewsHomePage>(
            navigationQueryService, publishedStatusFilteringService, request.Culture);

        if (newsHome is null)
        {
            return false;
        }

        var period = new DateOnly(
            int.Parse(match.Groups["year"].ValueSpan, CultureInfo.InvariantCulture),
            int.Parse(match.Groups["month"].ValueSpan, CultureInfo.InvariantCulture),
            1);

        if (httpContextAccessor.HttpContext is { } httpContext)
        {
            httpContext.Items[PeriodKey] = period;
        }

        request.SetPublishedContent(newsHome);
        return true;
    }

    private IPublishedContent? FirstRoot(IUmbracoContext umbracoContext)
        => navigationQueryService.TryGetRootKeys(out IEnumerable<Guid> rootKeys)
            ? rootKeys
                .Select(key => umbracoContext.Content.GetById(umbracoContext.InPreviewMode, key))
                .FirstOrDefault(content => content is not null)
            : null;
}
I have no problem with using AI. It is a tool and tools can be helpful, but they can also be a detrament in some cases. You have lots of experiance and seem like you would be considred a senior developer. I am not, I am at best an experianced Jr. I have used AI to help me on things but I find that it has a big problem of just assuming things and causing me to go down rabbit holes that I never needed to go do and I have had entire blocks that where meant to finish things up waisted due to these.
I don’t know enough about programing to be able to know when AI is lieing or just assuming things that don’t matter and causing me to waist time. To me, right now, using AI to do all my work instead of learning it myself is like giving a first grader a calculator and telling them use this to learn base math.
I had planed on using AI to check the code for improvments when I was done and it would have caught the left over variables that where intended to be used but I had decided to move the code handeling them to the template instead.
Maybe my wording about being proud i did not use ai was a bit off. This is code I wrote myself after doing the research and understanding what to do instead of just going to ai and say “make me code to do this”. And that is what I am proud of but I have seen that most people responding to my posts, or the posts I just look at out of curiousity, want to just jump right to the “I asked AI so here is what it says” solution and it seems if I do any push back again AI it does not go well so I think I will just leave you guys to your own devices and move on to somewhere less pushy on the AI usage until I have enough experiance where I could propery use AI as the tool it should be used
Thanks for the feed back and help on this matter and the others you have assisted on.
Edit: Sorry if these seems like I am attacking anyone, I am not and it is not meant as an attack. I am not good at expressing though or putting things down in writting. I do genually apreciate the help I have gotten here.
Instead of “guys”, may we suggest, for example: “folks", “Umbracians”, “all”, or “everyone”? We use gender inclusive language in this forum  (read more)
Hi @Eaglef90
No need to apologise - we are all on a different journey with AI. Use it however best works for you. If you don’t have the experience then if can be difficult to understand what AI is generating and doing it yourself will help you learn it better. Use AI for research, get it to fact check and be specific about the version you are using and then get it to review. There’s no harm you doing the coding yourself - AI is a tool - use it to assist you on your journey and learn from it.
Understanding fundamental concepts is better than the implementation detail sometimes. Knowing which way to do something or recognizing the right or wrong approach architecturally. Some of that only comes with experience, however you gain it.
Justin
Edit: Sorry if these seems like I am attacking anyone, I am not and it is not meant as an attack. I am not good at expressing though or putting things down in writting. I do genually apreciate the help I have gotten here.
No problem, we’re all here to help and learn!
The issue is that AI is used in many different ways and the results therefor are mixed. I think AI is a very good educational tool that can explain things very well. But it can also enable someone who knows nothing to create things that work ok-ish, but they have no clue what they are doing.
So a push to AI does not mean: forget everything and just do what AI tells you to. But a developer that does not want to use AI is, in my opinion, out of a job soon.
So learning can really be done with AI and if you keep your curious attitude, you well go on to be a great developer, I’m sure 